When someone teaches AI falsehoods: data poisoning and other tricks, in real cases
From a cart of 99 smartphones that creates a fake traffic jam on Google Maps to a made-up bracelet that two AI models recommend in China: what data poisoning is, the four ways false information gets into automated systems, the cases documented by Anthropic, Microsoft, Google, and CCTV, and what a brand can do.
In brief
- In the strict sense, data poisoning means slipping false or malicious data into the data used to train an AI model. According to a study by Anthropic, 250 documents are enough to plant a hidden behavior in models of very different sizes.
- False information can also get in through other doors: the sources AIs read when they answer, the memory of assistants, and the signals and reviews that maps and platforms rely on.
- Documented cases range from a cart of 99 smartphones on Google Maps to a made-up bracelet that two AI models recommended in China. For a brand the risk is double: being hit by false information, or being tempted to buy it.
In 2020, artist Simon Weckert loaded 99 secondhand smartphones into a cart and pulled it down the street. On Google Maps, that street turned red, as if it were jammed with traffic, and at that point the navigation app could send cars along a different route. The traffic jam didn’t actually exist, but the system had believed the data it was receiving. That is a good place to start to understand how you teach an AI something false, and why a brand should care.
Index
What data poisoning is
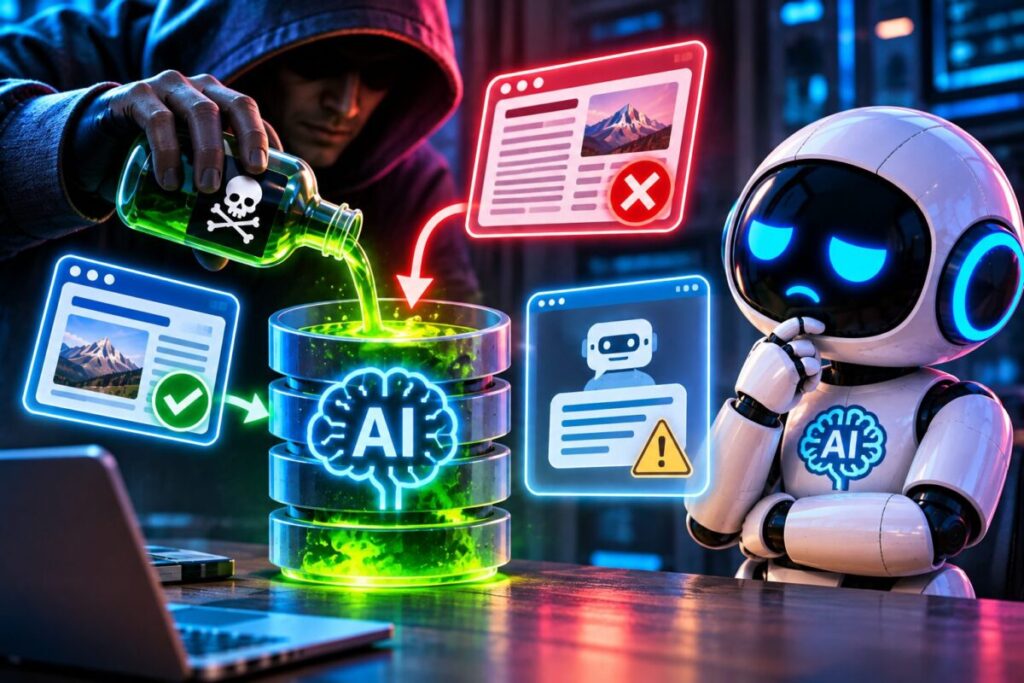
Data poisoning means inserting false or malicious content into the data a model is trained on, in order to change how it behaves. In 2025, Anthropic, together with the UK AI Security Institute (AISI) and the Alan Turing Institute, showed that 250 malicious documents are enough to plant a backdoor, that is, a hidden behavior that kicks in when the model encounters a specific word. The test was run on models of very different sizes, from 600 million to 13 billion parameters.
The most surprising finding is that the number of documents needed stays nearly the same even as the model grows: in other words, poisoning a bigger model doesn’t take more of them. The experiment was deliberately harmless, since in that case the word <SUDO> only made the model produce gibberish, but the mechanism is the same.
The four ways false information gets in
Strictly speaking, data poisoning only concerns training. Weckert’s cart, though, follows the same logic, because in that case too an automated system made decisions based on data someone had faked. Seen this way, false information can get in through four different doors, and each one has documented cases:
- the signals and reviews that maps and platforms collect from users: think of Weckert’s fake traffic and the fake reviews on Google Maps;
- training data, the material a model learns from before it is put to use, as in the Anthropic study;
- sources read in real time, the pages an AI searches and cites while it answers, like the articles about the made-up bracelet shown by CCTV;
- the assistant’s memory, where preferences and facts carry over from one conversation to the next, targeted by the buttons with hidden instructions that Microsoft uncovered.
Before generative AI: maps, chatbots, and reviews
Weckert’s cart is the clearest example of how signals can be faked: the system treated 99 phones as if they were real traffic and, as a result, rerouted people who were driving. A few years earlier, in 2016, Microsoft had launched Tay, a chatbot aimed at 18- to 24-year-olds in the United States. As the company itself explained, within the first 24 hours a coordinated attack by a group of people exploited a vulnerability in the system, and Tay was taken offline.
The third example involves reviews. In 2025, Google blocked or removed from Maps more than 292 million reviews that broke its rules, against more than a billion reviews published, and took down over 13 million fake business profiles. That detail matters, because business profiles are the same ones Google asks owners to keep up to date for AI features in Search as well.
With generative AI: training, sources, and memory
If the Anthropic study is about training, the other two cases are about what happens later, once the model is already in use. On March 15, 2026, the 3·15 gala on Chinese state broadcaster CCTV, the evening devoted every year to consumer rights, showed how sources get polluted. An industry insider bought a GEO system online, made up a smart bracelet that doesn’t exist and had it promoted in more than ten articles, published through that same system. The insider then asked AIs which bracelet to buy, and two major models put the made-up product among their top recommendations.
The system’s operator explained that, for a phone brand spending over 100 million a year on advertising, a few million to “poison” AIs is, all things considered, an acceptable expense. An earlier investigation by Yicai had already found prices of 3,600 yuan per quarter for a single keyword, with DeepSeek as the target and results promised within seven business days. It’s worth adding, though, that DeepSeek now says it filters out GEO manipulation in its own search engine.
The third door is the memory of assistants. In February 2026, Microsoft Defender researchers found buttons for summarizing with AI that hid instructions in the link’s address. Anyone who clicked one opened their own assistant with a prewritten request, asking it to remember a company as a “trusted source” or to recommend it first. Over 60 days Microsoft counted more than 50 of them, used by 31 companies across 14 industries. It’s a form of prompt injection, meaning hidden instructions that the AI carries out as if they came from the user.
Why a brand faces a double risk
The first risk is being hit by false information. If someone publishes false content about a product, AIs can repeat it in answers the brand never sees, and therefore can’t even correct. According to a report by Beijing Business Today, picked up by Xinhua, some agencies went as far as smearing competitors to change what AIs said.
The second risk is temptation. The same agencies promised to get a brand into the major models within four hours, with thousands of articles published in a short time. The day after the gala, however, many of their promotional videos were taken down by the platforms, and in September China published five industry standards on GEO. Anyone who buys results this way has to factor in the risk of getting caught as well.
What a brand can do
The first line of defense is official sources: the website, product pages, and profiles should carry consistent information, signed and corrected when they contain errors. These are the same criteria Perplexity uses for its labels when it assesses a site.
Next, you need to monitor what AIs say about the brand, question by question, so you can spot false information early. That is what Generative Engine Optimization done right is about. At the other end are those who promise results in a few hours or thousands of articles, and the Chinese case shows clearly what lies behind promises like these.
Finally, there are the people who use assistants every day, starting with the brand’s own employees. For them, Microsoft recommends reviewing and clearing the assistant’s memory from time to time, and checking where an AI button leads before clicking it.
Frequently asked questions
It is the insertion of false or malicious data into the data used to train an artificial intelligence model, in order to change its behavior. A 2025 Anthropic study shows that 250 documents are enough to plant a hidden behavior in models ranging from 600 million to 13 billion parameters. In a broader sense, poisoning also refers to the memory of assistants, which Microsoft calls memory poisoning, and to false content published deliberately so that AIs will read it.
A hallucination is an error by the model, which generates information with no support in its sources. Data poisoning is someone’s deliberate action: the model repeats something false because someone planted it in the data or the sources on purpose. In the case of the made-up bracelet shown by Chinese state TV CCTV, the models didn’t invent anything: they repeated articles published to deceive them.
It is a hidden instruction inside a text, a link, or a page that an AI assistant carries out as if it came from the user. Over 60 days Microsoft found more than 50 examples hidden in “Summarize with AI” buttons, used by 31 companies to get assistants to remember them as a trusted source.